

What is being compared?
For each prediction request or agent execution in scope:- The platform loads the original structured response from durable storage.
- It loads ground truth from feedback: JSON in the
responsefield, or JSON inferred from notes when Infer corrections is on. - It runs one or more evaluators on each pair and aggregates metrics.
How responses are flattened
Scoring flattens model output and ground truth into dotted leaf paths. Examples:vendor_name, address.city, total_amount.
- Lists are atomic. The whole list is one leaf.
line_itemsis notline_items[0].description.field_accuracyuses exact equality.fuzzy_field_matchJSON-serializes both sides and scores similarity.llm_judgescores the list semantically. _metadatakeys are skipped. A key that contains_metadata(_metadata,name_metadata) is never scored.- Null ground truth is excluded by default. A leaf whose corrected value is
nullis left out of the metric. Setskip_null_expectedtofalseto score explicit nulls.
Run an evaluation in the dashboard
Store corrections with Feedback & fine-tuning first. Tie each correction to a request or execution ID. The run is asynchronous. You get a run record immediately. Scores fill in when scoring finishes.1
Open Evaluations
In the dashboard sidebar, choose Evaluations. It sits with Overview, Requests, Executions, and Completions.
2
Start an evaluation and choose a source
Click New Evaluation. Pick a source: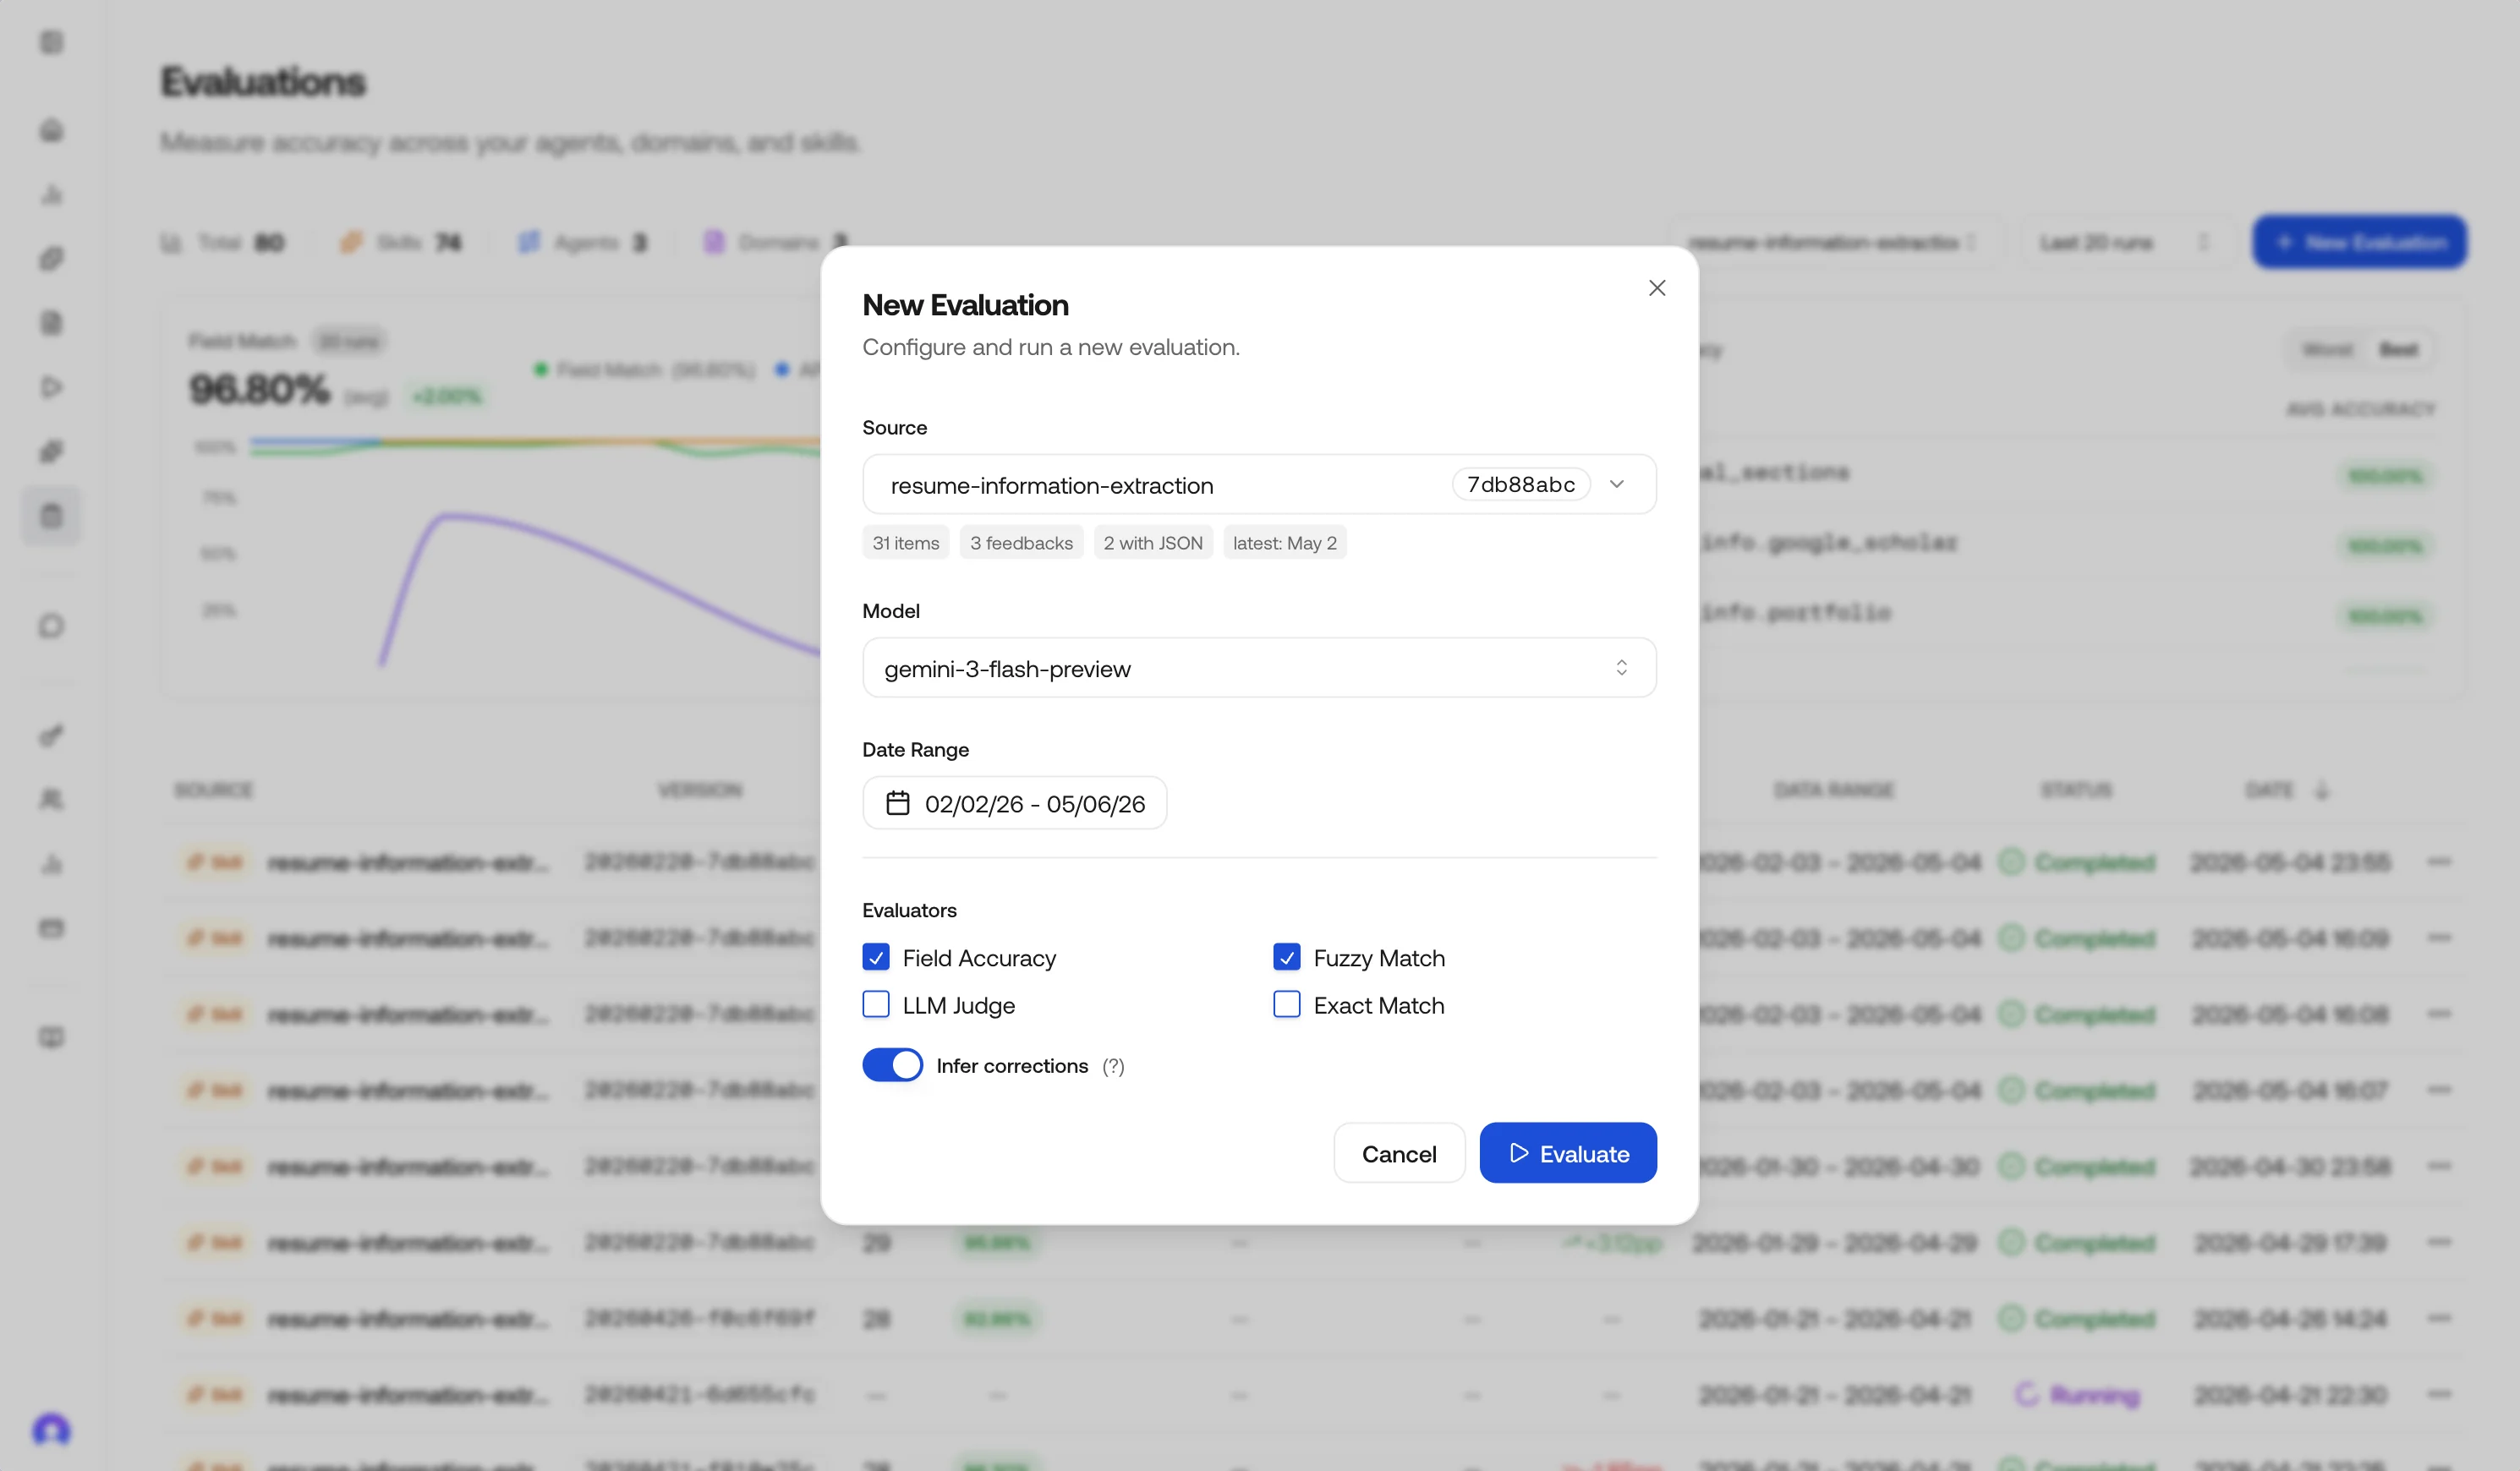
- Skill: one skill ID. Scores prediction requests and agent executions that used that skill in the date range.
- Agent: one agent ID and version. Scores agent executions in range.
- Request domain: a hub domain on requests, for example
document.invoice. Scores prediction requests for that domain.
3
Set the date range
Choose the time window. The preview shows total items, items with feedback, items with JSON corrections, and the latest activity timestamp.A very wide window mixes old prompts with new ones and blurs trends.
4
Pick a model (optional)
Choose an inference model to limit the run. Examples:
gemini-3.1-flash-lite-preview, gemini-3.1-pro-preview, vlm-1. Only requests and executions from that model are loaded.Default (auto-detect) scores every item in the window. The selected model is the model Rerun uses when it skips inference.5
Choose evaluators
Select one or more strategies. The default emphasis is Field accuracy. Tradeoffs are in Evaluator types.
6
Select fields (optional)
Pass top-level keys or dotted leaf-path prefixes to limit scoring. Examples:
vendor_name, address, line_items. Omit the list to score every field.Matching rules are in Field selection.7
Infer corrections (optional)
Infer corrections is on by default. Notes-only feedback can be turned into JSON with an LLM. The skill schema is used when one is available.
Inferred JSON is best-effort. For production ground truth, send explicit JSON in feedback. See Feedback & fine-tuning.
8
Run
Submit the run. Status starts at
running, then moves to completed or failed. The dashboard polls every few seconds. The result view unlocks at completed.Review results
Open a completed run from the history table.- Overall accuracy: field-level matches versus mismatches. Samples without corrections use an accepted assumption in this rollup.
- Accuracy delta: change versus the previous completed run with the same source label and type.
- API completion rate: share of in-scope items whose upstream API calls completed. Failed and incomplete calls count against the rate.
- Total samples: items in this run.
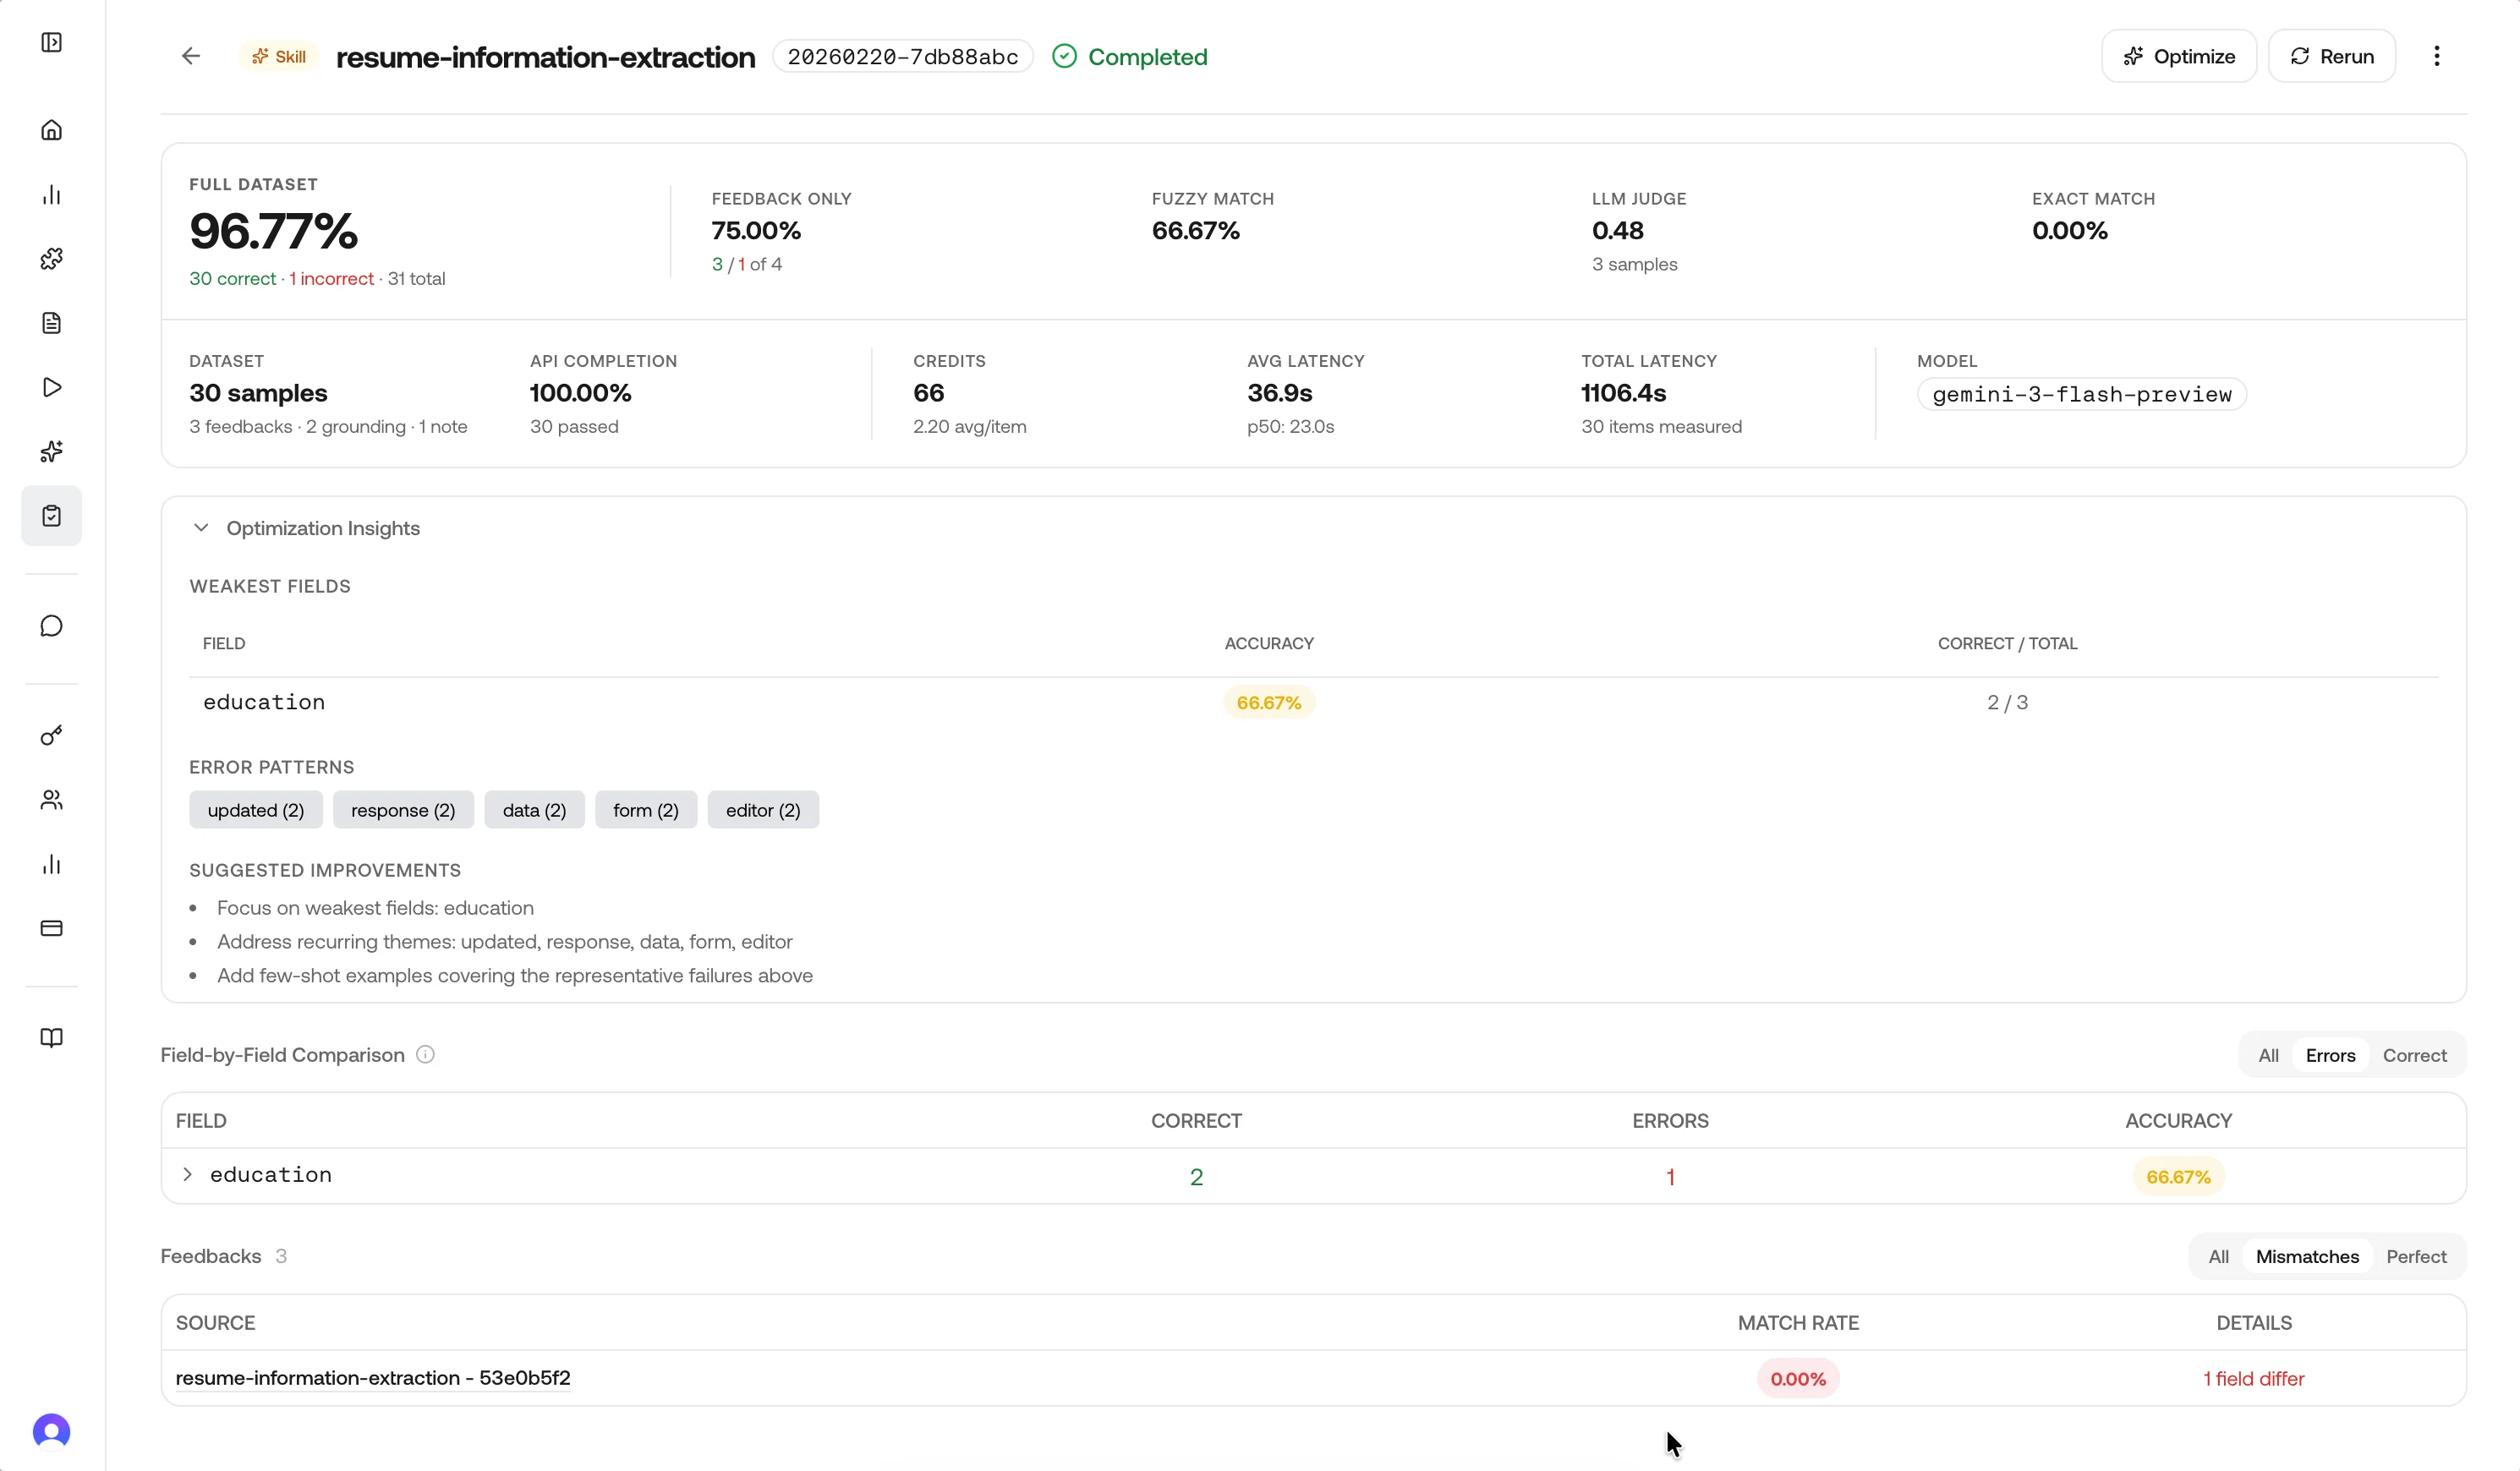
Performance metrics
Completed runs include cost and latency of the underlying API traffic.
The same numbers fill the Credits and Model columns in the history table. VS Prev shows the field-match delta versus the previous run.
Field breakdown
Field-by-Field Comparison lists each extracted field.Use the row filters at the top right—All, Errors, or Correct—to narrow the table. Errors shows fields that still mismatch.
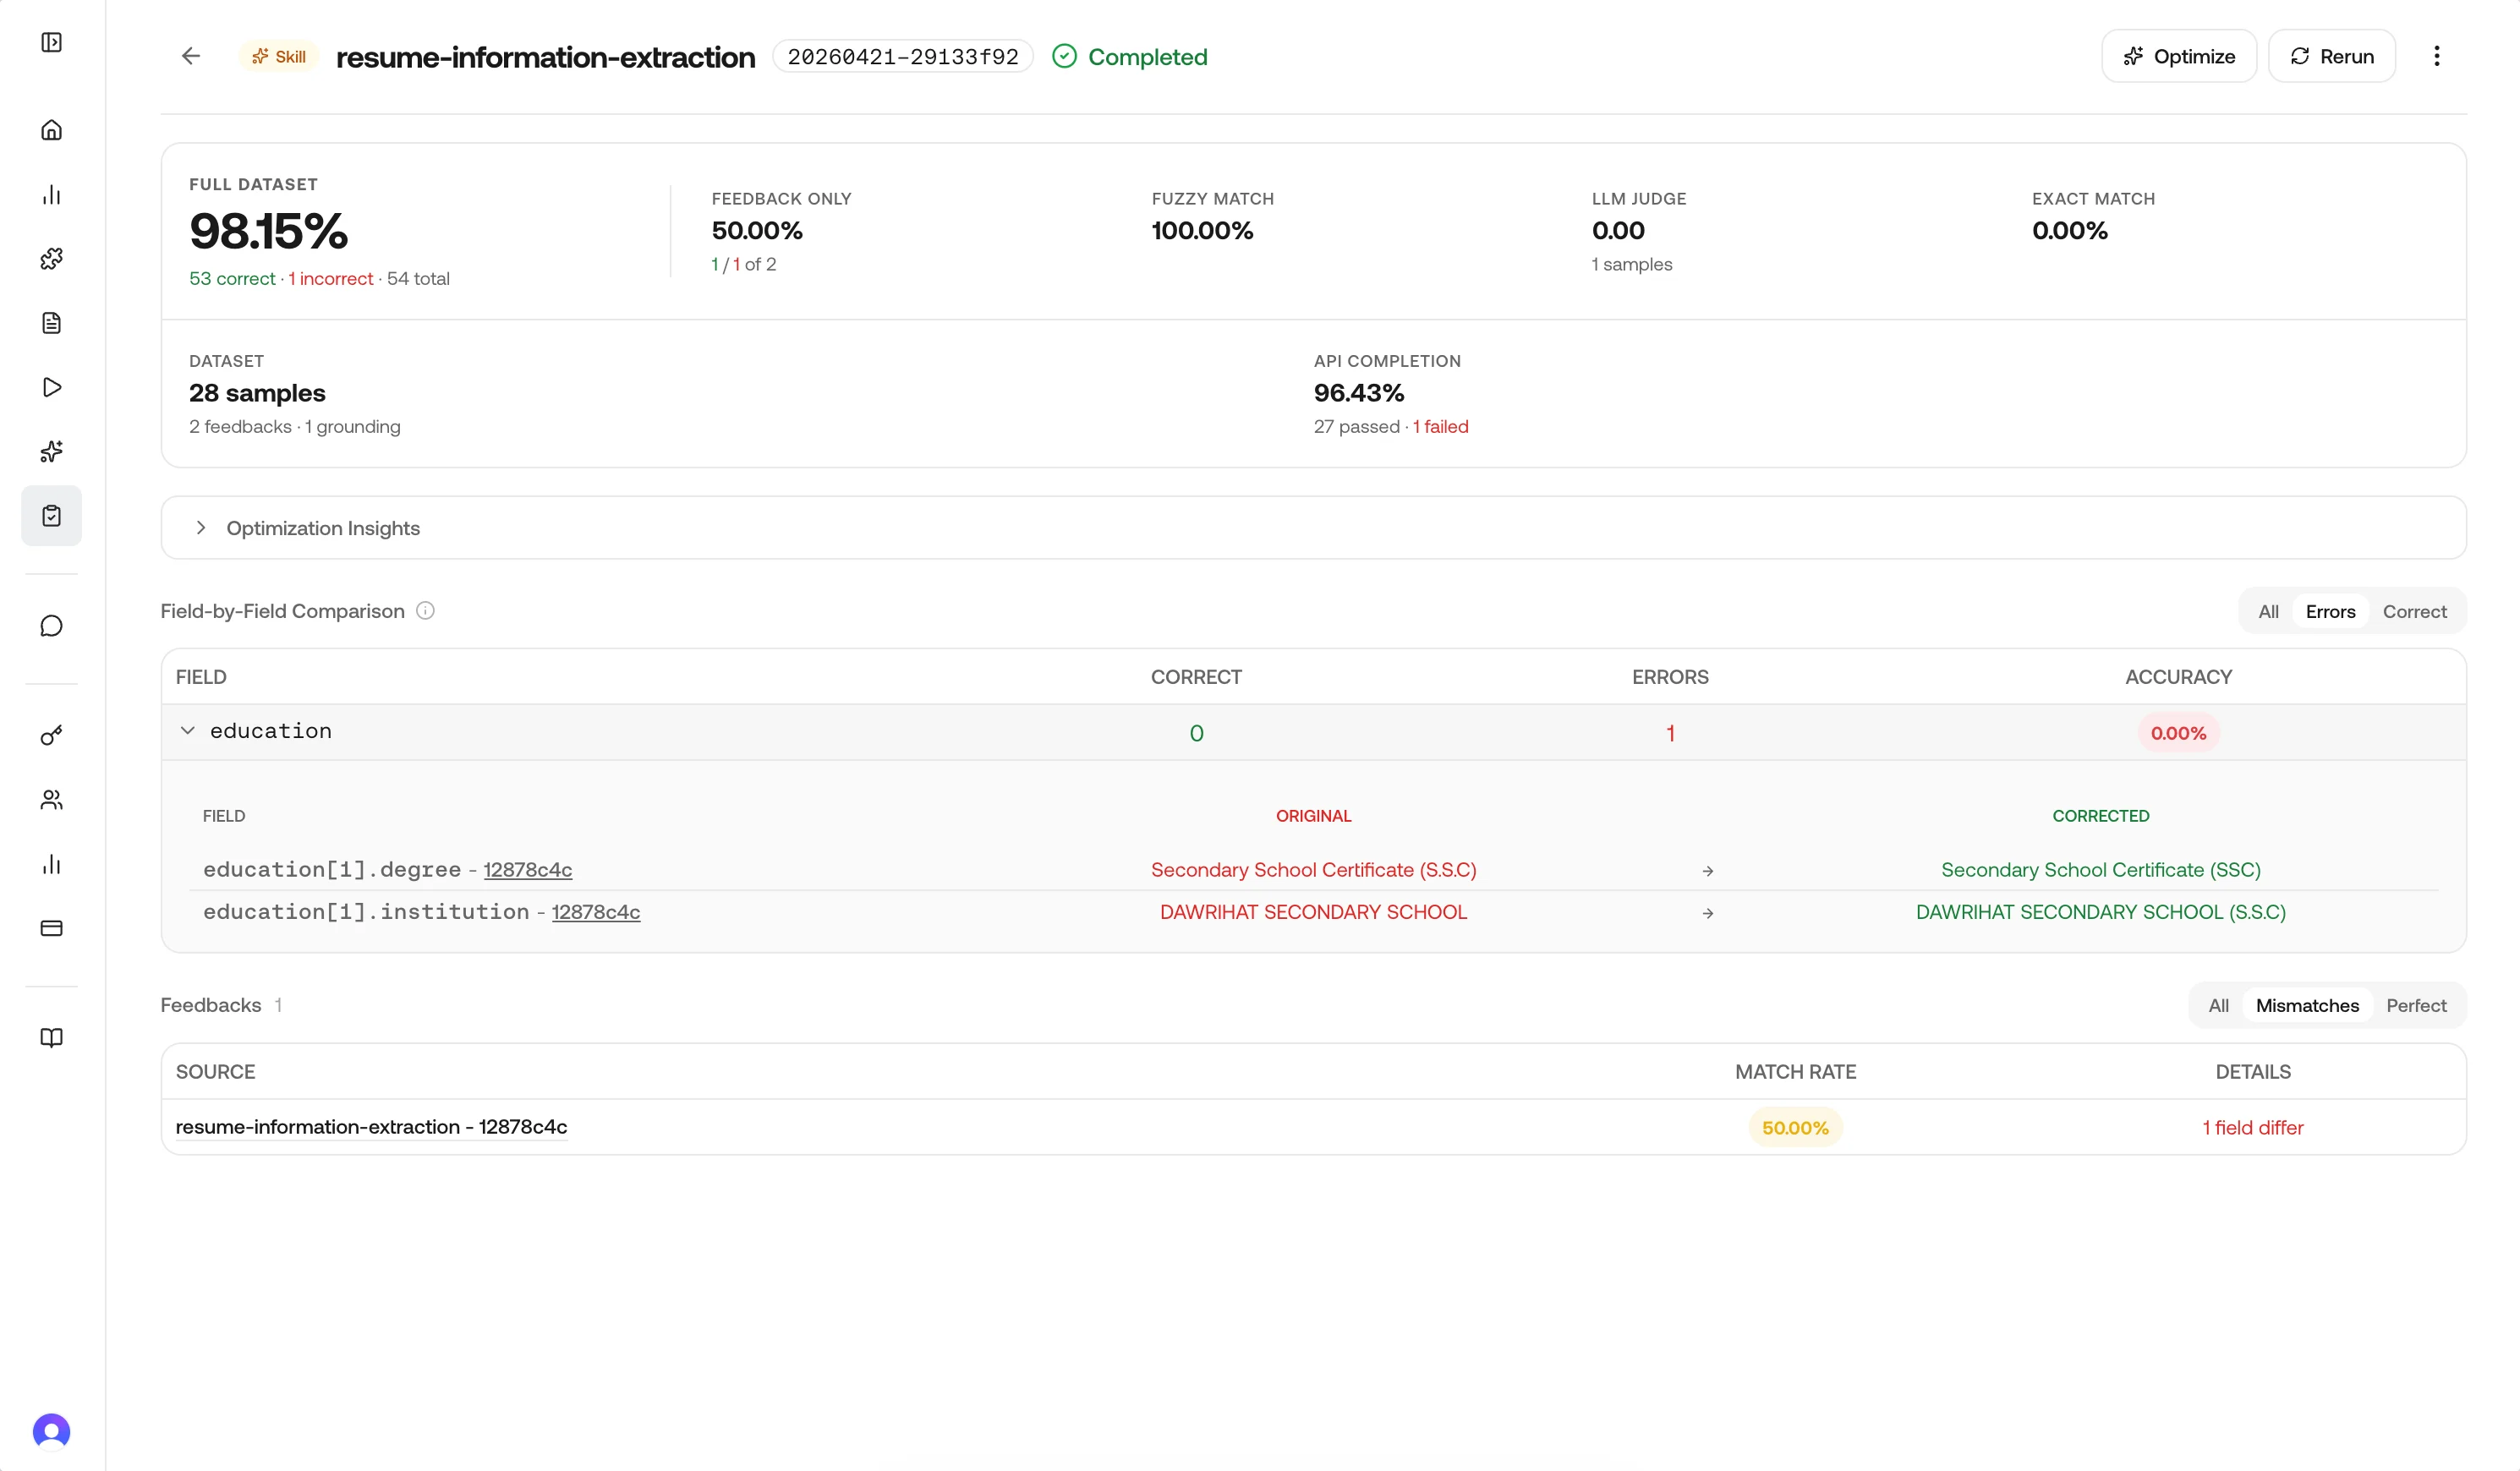
Rows put the weakest fields first. Expand a field for Original (model output) and Corrected (feedback).
Optimization hints (skill runs only)
Skill runs can include optimization hints: weakest fields, themes from notes, a few representative failures, and short next steps. Read them before Optimize. Optimize uses those inputs when it creates a new skill version.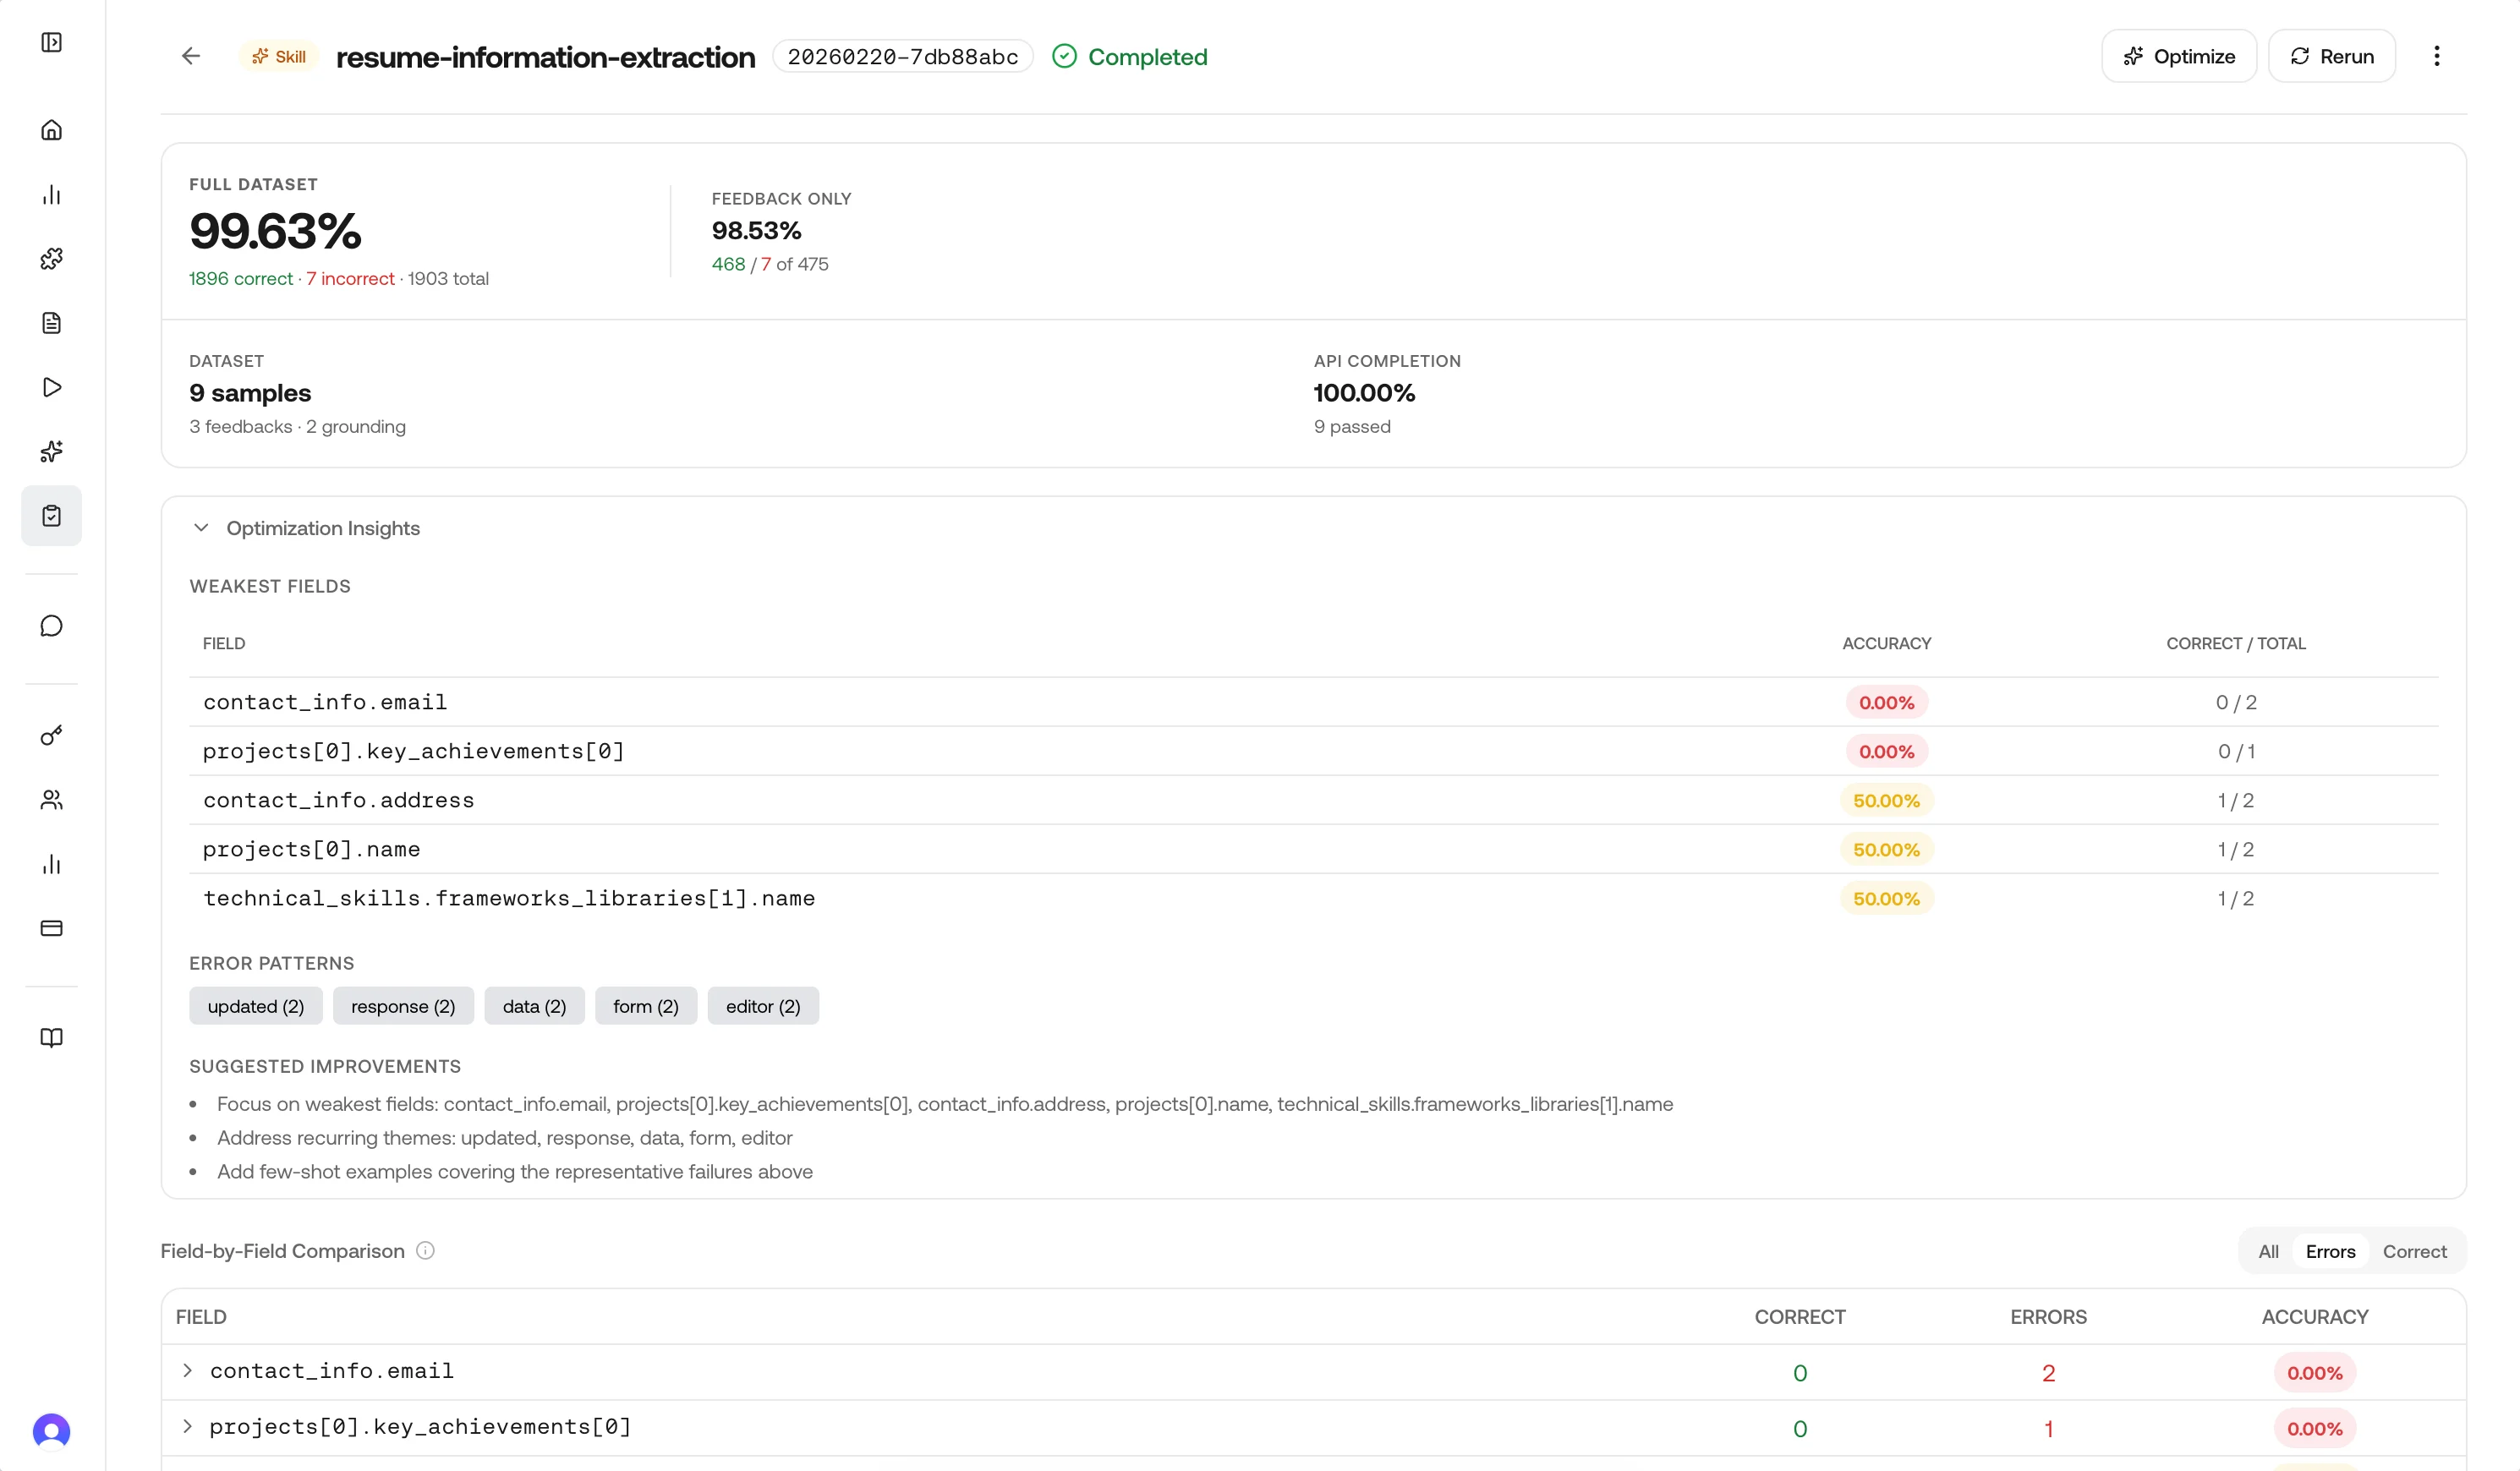
Metrics and history
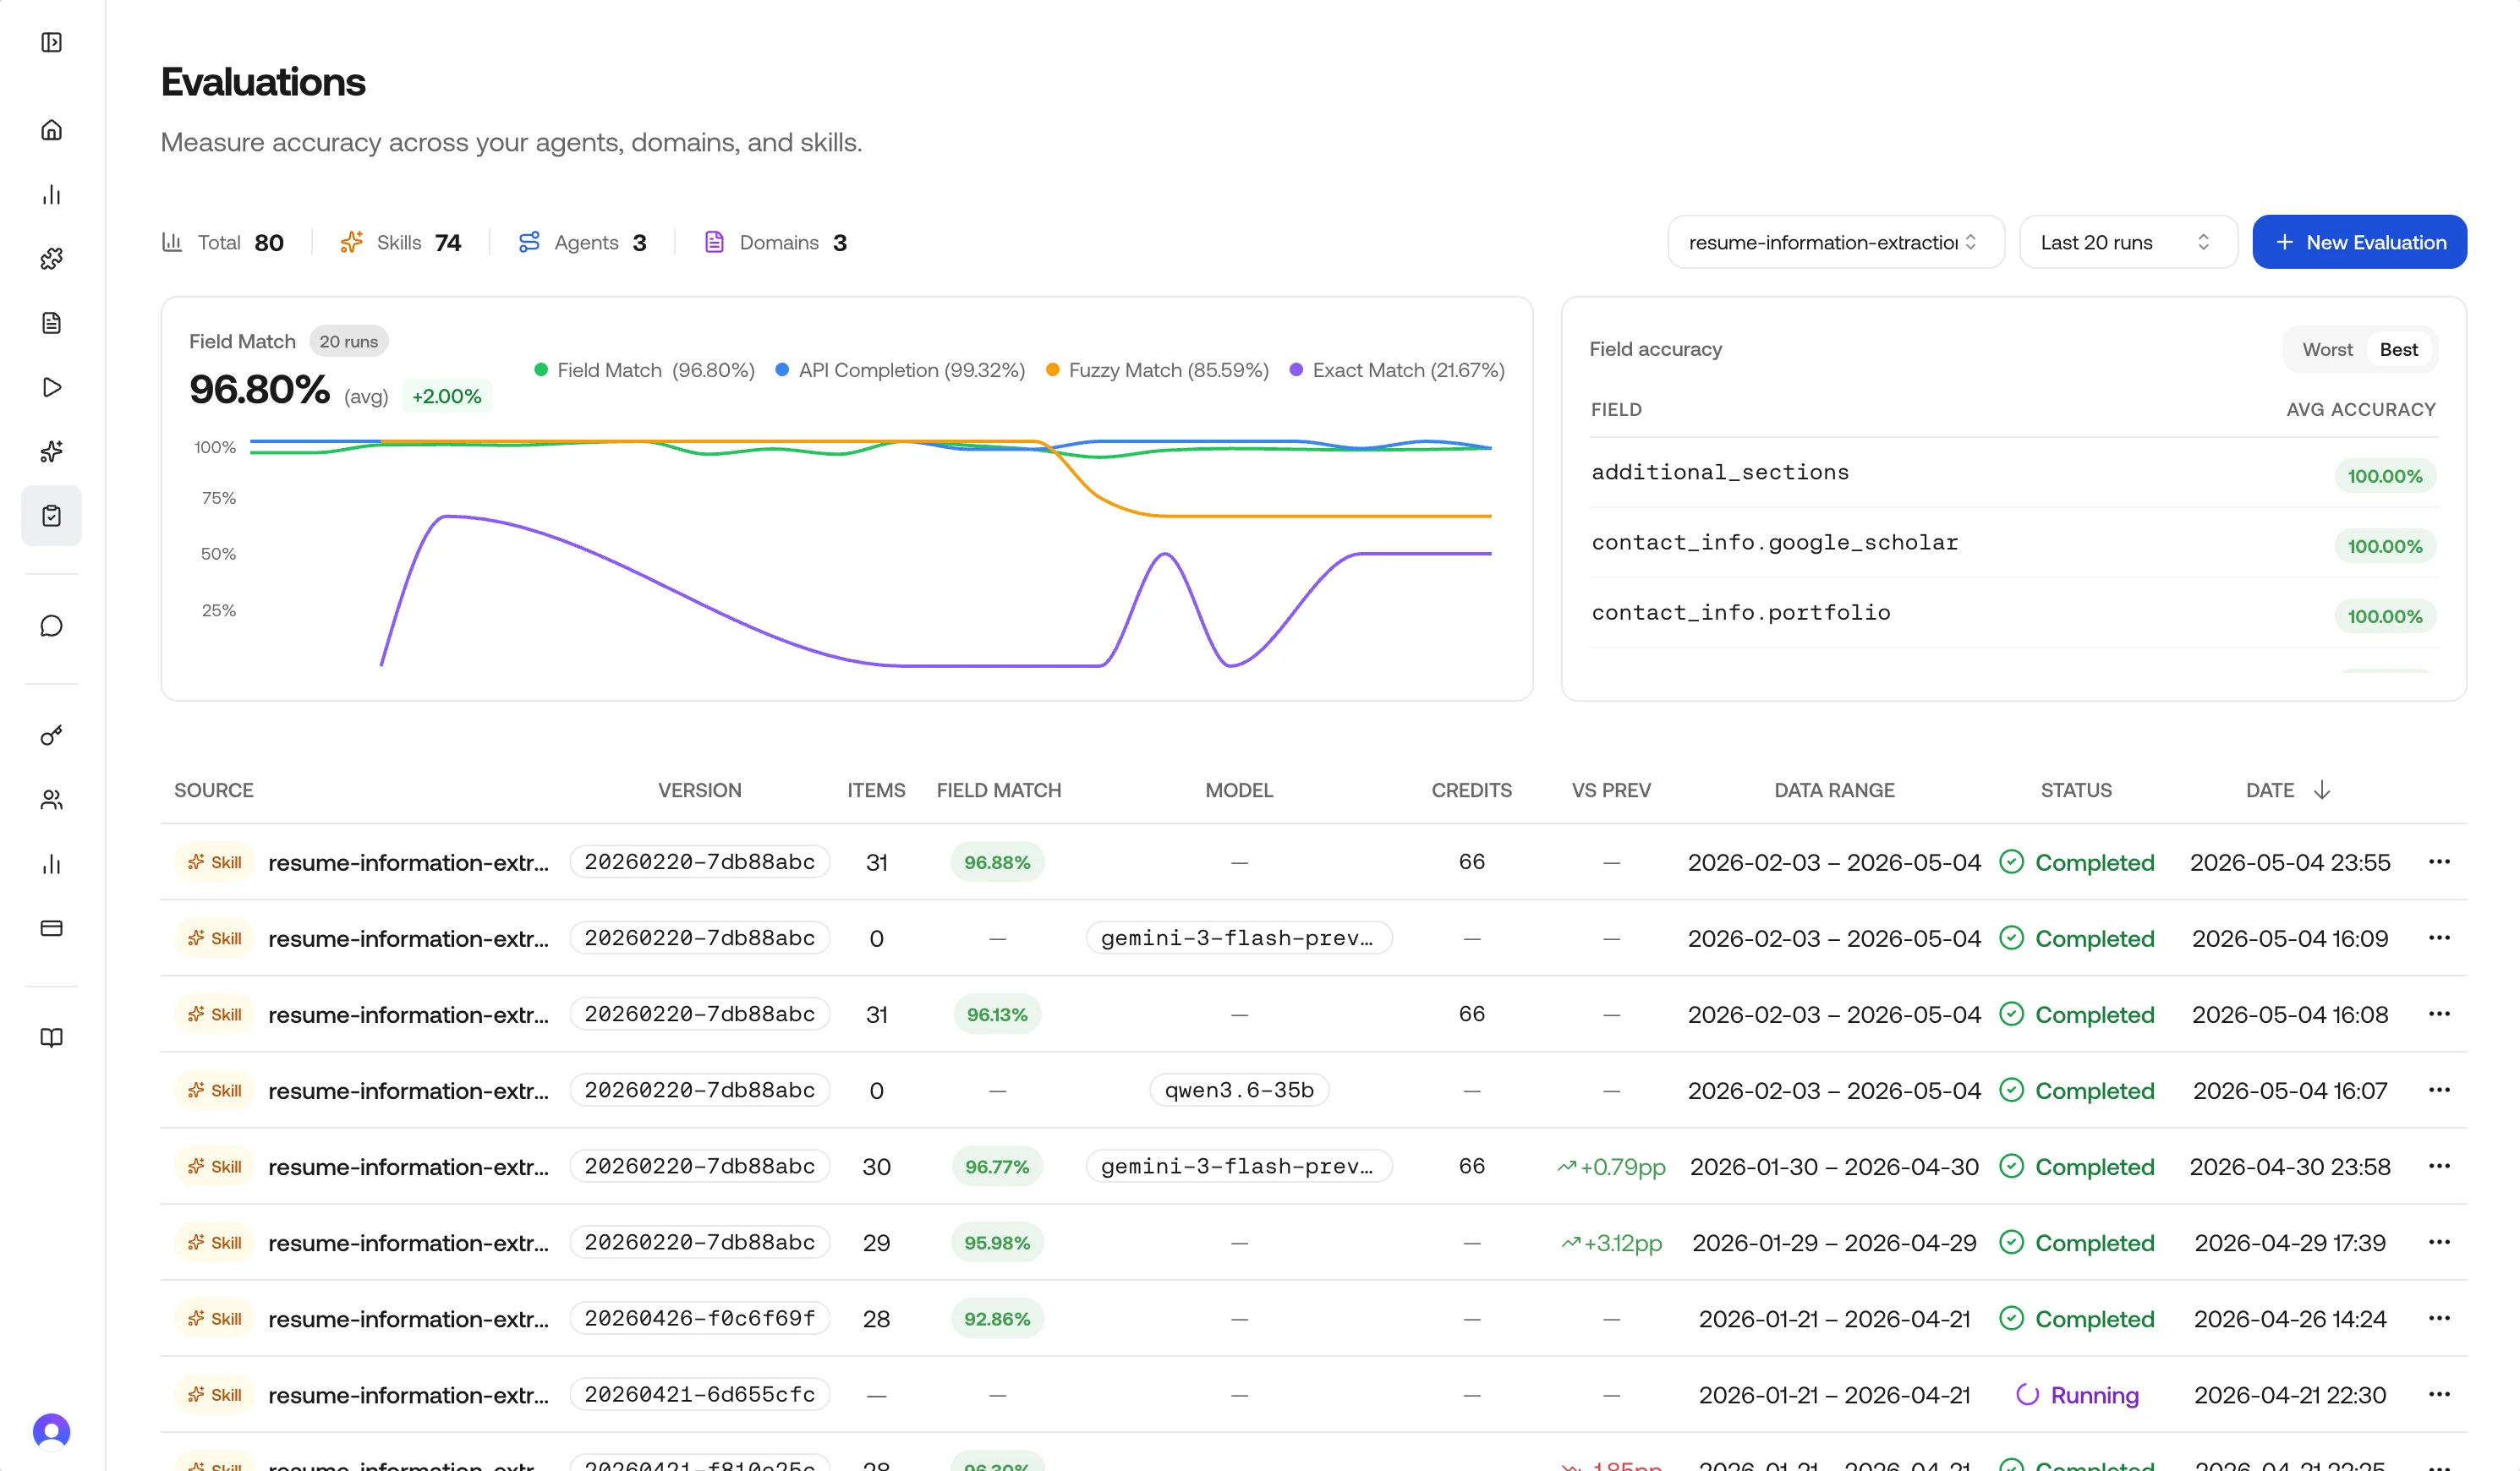
- Summary cards: total runs, plus counts for Skills, Agents, and Domains.
- Accuracy trend: field-match accuracy across recent completed runs, filterable by source. Overlays can show API completion rate, fuzzy-match rate, and exact-match rate when those evaluators ran.
- Cross-run field view: weakest fields across history, with a Worst / Best toggle.
- History table: status, source, model, credits, field-match accuracy, VS Prev delta, data range, and timestamps. Row actions depend on status and source type.
Evaluation sources (API naming)
The preview endpoint uses the same identifiers. Check counts there before you run.
Evaluator types
You can combine evaluators in one run.Field accuracy (field_accuracy)
This score drives the field table and optimization hints.
Fuzzy field match (fuzzy_field_match)
String leaves take the higher of character-level and token-level similarity. A leaf passes at similarity ≥ 0.7.
LLM judge (llm_judge)
Each sample gets a semantic score from 0 to 1. Use it when paraphrases or layout differences should not count as errors. The judge adds model latency and cost compared with the deterministic evaluators.
Exact match (equals_expected)
Leaves must match exactly, including whitespace and casing. Only expected strings of ≤ 128 characters are included. Longer leaves are skipped. If no leaf qualifies, the sample can be omitted from the exact-match rate.
LLM judge and Exact match are independent toggles. Turning on the judge does not replace exact match. Choose both only when you want both signals.
Choosing a combination
Field selection
By default, every field in the JSON output is scored. Pass afields list of top-level keys or dotted leaf-path prefixes to limit scoring.
Lists are not recursed into. A leaf prefix like
line_items matches the list itself, not line_items[0].description. To compare list contents semantically, enable LLM judge alongside field_accuracy.fields and other run options in the run or rerun body:
fields is omitted or null, all fields are evaluated. That default is backward-compatible. On Rerun, omitted evaluators, infer_corrections, and skip_null_expected are inherited from the original run’s stored config.
Interpreting accuracy
Actions on a run
Optimize (skill evaluations only)
Optimize is available whensource_type is skill and the run status is completed. The service samples up to 30 response/correction pairs by default. The API allows up to 200. It calls the skill optimizer with a Gemini model and creates a new skill version with the same name.
The optimizer writes:
- A prompt addendum appended to the original prompt. It captures generic error patterns and includes no actual data values.
- Per-field schema hints on the JSON Schema descriptions for the fields with the most errors.
Rerun (skill evaluations only)
Rerun is skill-only in the UI. It calls the platform rerun pipeline:- Optimizes the source skill first unless you pass a different skill via API.
- Re-executes the underlying requests and executions against the new skill, swapping the model when one was selected.
- Copies feedback forward onto the new request and execution IDs. It infers corrections from notes when that option is enabled.
- Re-scores the new traffic and writes the result to a fresh run row.
evaluators, fields, infer_corrections, or skip_null_expected on the rerun request to inherit them from the original run’s stored config. Pass any of them to override. You can re-score the same window under different conditions, for example evaluators set to ["llm_judge"], without rebuilding the full request.
Agent and domain evaluations still return metrics and samples. Optimize and Rerun are hidden because those flows need a skill to re-execute against.
Delete
Delete removes the run record. It is typically allowed for completed or failed runs. It does not delete requests, executions, or feedback.Programmatic feedback
Evaluations read feedback you already stored. They do not replace the feedback API. Submission formats, entity IDs (request, agent_execution, chat), and examples are in Feedback & fine-tuning and Submit feedback.
Dashboard run, optimize, and rerun call internal evaluation services. Those routes are not in the public api.vlm.run OpenAPI bundle. Use the dashboard unless your integration team has exposed the same routes.
Related pages
Feedback & fine-tuning
Ground truth tied to requests and executions.
Submit feedback API
HTTP reference for structured feedback.