

Source video for trim, sample, and keyframe examples
Example Usage
Use the Structured Outputs API for structured, validated responses.
1. Video Frame Sampling
Pass an interval or specific timestamps.Extract at least 3 frames from the video for thumbnail generation.
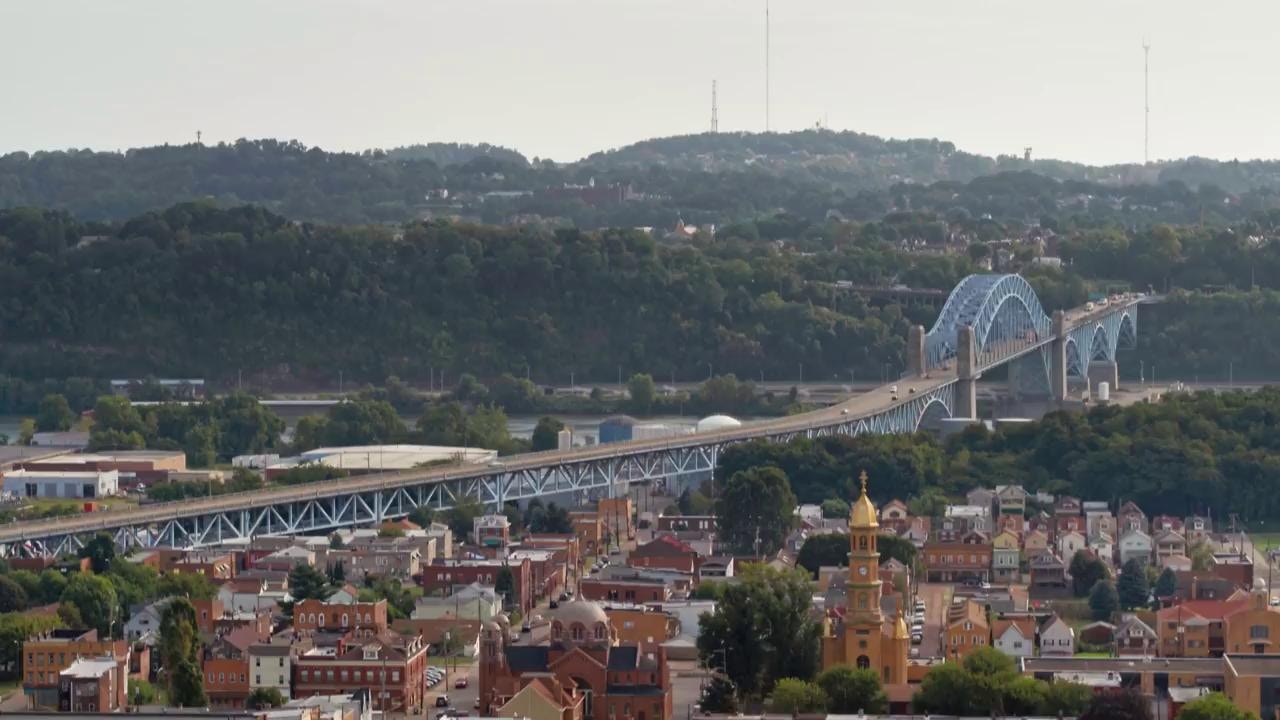
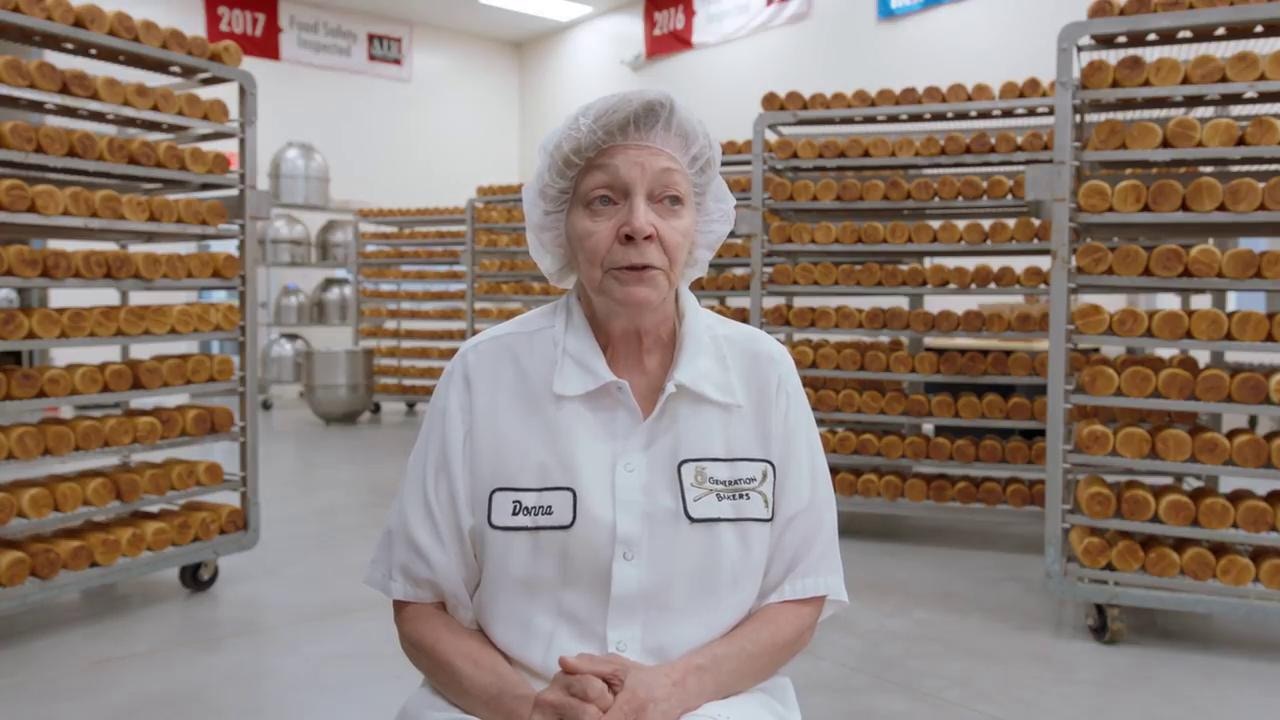
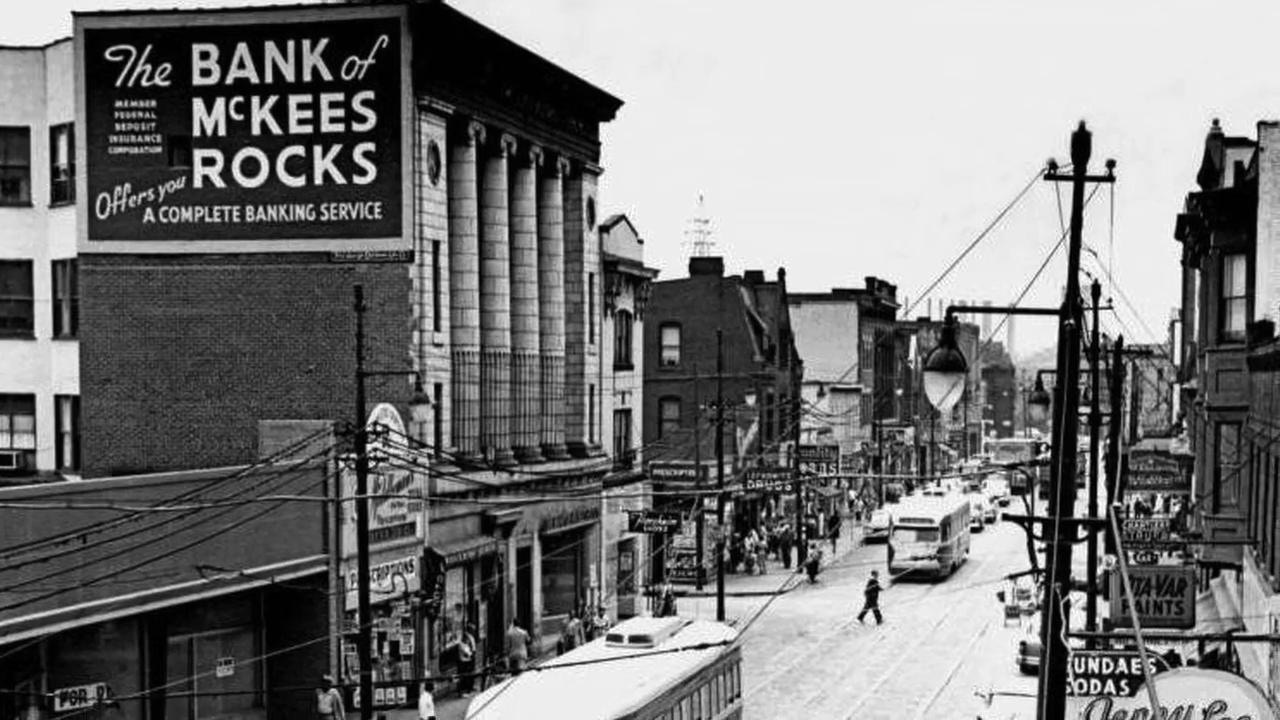
Three frames sampled for thumbnails.
from vlmrun.client import VLMRun

# Initialize the VLMRun client
client = VLMRun(api_key="<VLMRUN_API_KEY>")

# Extract keyframes for thumbnails
response = client.agent.completions.create(
    model="vlmrun-orion-1:auto",
    messages=[
        {
            "role": "user",
            "content": [
                {"type": "text", "text": "Extract keyframes from this video for thumbnail generation, sampling every 5 seconds"},
                {"type": "video_url", "video_url": {"url": "https://storage.googleapis.com/vlm-data-public-prod/hub/examples/video.transcription/bakery.mp4"}}
            ]
        }
    ]
)

print(response.choices[0].message.content)
# >>> {"frames": [{"url": "https://.../frame-1.jpg", "timestamp": "00:00:00.000"}, ...]}
from vlmrun.client import VLMRun
from pydantic import BaseModel, Field

# Define the response schema
class VideoFrame(BaseModel):
    url: str = Field(..., description="The URL of the extracted frame")
    timestamp: str = Field(..., description="Timestamp in HH:MM:SS.MS format")

class VideoSamplingResponse(BaseModel):
    frames: list[VideoFrame] = Field(..., description="List of extracted frames")

# Initialize the VLMRun client
client = VLMRun(api_key="<VLMRUN_API_KEY>")

# Extract keyframes with structured output
response = client.agent.completions.create(
    model="vlmrun-orion-1:auto",
    messages=[
        {
            "role": "user",
            "content": [
                {"type": "text", "text": "Extract keyframes from this video for thumbnail generation, sampling every 5 seconds"},
                {"type": "video_url", "video_url": {"url": "https://storage.googleapis.com/vlm-data-public-prod/hub/examples/video.transcription/bakery.mp4"}}
            ]
        }
    ],
    response_format={"type": "json_schema", "schema": VideoSamplingResponse.model_json_schema()}
)

# Validate the response
result = VideoSamplingResponse.model_validate_json(response.choices[0].message.content)
# >>> VideoSamplingResponse(frames=[VideoFrame(url="...", timestamp="..."), ...])
import { VlmRun } from "vlmrun";

const client = new VlmRun({
  apiKey: "<VLMRUN_API_KEY>",
  baseURL: "https://api.vlm.run/v1"
});

const response = await client.agent.completions.create({
  model: "vlmrun-orion-1:auto",
  messages: [
    {
      role: "user",
      content: [
        { type: "text", text: "Extract keyframes from this video for thumbnail generation, sampling every 5 seconds" },
        { type: "video_url", video_url: { url: "https://storage.googleapis.com/vlm-data-public-prod/hub/examples/video.transcription/bakery.mp4" } }
      ]
    }
  ]
});

console.log(response.choices[0].message.content);
import { VlmRun } from "vlmrun";
import { z } from "zod";
import { zodToJsonSchema } from "zod-to-json-schema";

// Define the response schema with Zod
const VideoSamplingResponseSchema = z.object({
  frames: z.array(z.object({
    url: z.string().describe("The URL of the extracted frame"),
    timestamp: z.string().describe("Timestamp in HH:MM:SS.MS format")
  })).describe("List of extracted frames")
});

// Initialize the VLMRun client
const client = new VlmRun({
  apiKey: "<VLMRUN_API_KEY>",
  baseURL: "https://api.vlm.run/v1"
});

// Extract keyframes with structured output
const response = await client.agent.completions.create({
  model: "vlmrun-orion-1:auto",
  messages: [
    {
      role: "user",
      content: [
        { type: "text", text: "Extract keyframes from this video for thumbnail generation, sampling every 5 seconds" },
        { type: "video_url", video_url: { url: "https://storage.googleapis.com/vlm-data-public-prod/hub/examples/video.transcription/bakery.mp4" } }
      ]
    }
  ],
  response_format: {
    type: "json_schema",
    schema: zodToJsonSchema(VideoSamplingResponseSchema)
  }
});

const result = VideoSamplingResponseSchema.parse(JSON.parse(response.choices[0].message.content));
console.log(result);
// >>> { frames: [{ url: "https://.../frame-1.jpg", timestamp: "00:00:00.000" }, ...] }
2. Video Highlight Extraction
Extract the 3 best moments from this video, including the start and end times of each moment.
Three extracted highlights.
from vlmrun.client import VLMRun

# Initialize the VLMRun client
client = VLMRun(api_key="<VLMRUN_API_KEY>")

# Extract multiple segments
response = client.agent.completions.create(
    model="vlmrun-orion-1:auto",
    messages=[
        {
            "role": "user",
            "content": [
                {"type": "text", "text": "Extract the 3 best moments from this video, including the start and end times of each moment."},
                {"type": "video_url", "video_url": {"url": "https://storage.googleapis.com/vlm-data-public-prod/hub/examples/video.transcription/bakery.mp4"}}
            ]
        }
    ]
)

print(response.choices[0].message.content)
# >>> {"segments": [...]}
from vlmrun.client import VLMRun
from pydantic import BaseModel, Field

# Define the response schema
class HighlightVideo(BaseModel):
    start_time: str = Field(..., description="Start time in HH:MM:SS.MS format")
    end_time: str = Field(..., description="End time in HH:MM:SS.MS format")
    url: str = Field(..., description="URL of the extracted segment")

class HighlightExtractionResponse(BaseModel):
    segments: list[HighlightVideo] = Field(..., description="List of extracted segments")

# Initialize the VLMRun client
client = VLMRun(api_key="<VLMRUN_API_KEY>")

# Extract highlights with structured output
response = client.agent.completions.create(
    model="vlmrun-orion-1:auto",
    messages=[
        {
            "role": "user",
            "content": [
                {"type": "text", "text": "Extract the 3 best moments from this video, including the start and end times of each moment."},
                {"type": "video_url", "video_url": {"url": "https://storage.googleapis.com/vlm-data-public-prod/hub/examples/video.transcription/bakery.mp4"}}
            ]
        }
    ],
    response_format={"type": "json_schema", "schema": HighlightExtractionResponse.model_json_schema()}
)

# Validate the response
result = HighlightExtractionResponse.model_validate_json(response.choices[0].message.content)
import { VlmRun } from "vlmrun";

const client = new VlmRun({
  apiKey: "<VLMRUN_API_KEY>",
  baseURL: "https://api.vlm.run/v1"
});

const response = await client.agent.completions.create({
  model: "vlmrun-orion-1:auto",
  messages: [
    {
      role: "user",
      content: [
        { type: "text", text: "Extract the 3 best moments from this video, including the start and end times of each moment." },
        { type: "video_url", video_url: { url: "https://storage.googleapis.com/vlm-data-public-prod/hub/examples/video.transcription/bakery.mp4" } }
      ]
    }
  ]
});

console.log(response.choices[0].message.content);
import { VlmRun } from "vlmrun";
import { z } from "zod";
import { zodToJsonSchema } from "zod-to-json-schema";

// Define the response schema with Zod
const HighlightExtractionResponseSchema = z.object({
  segments: z.array(z.object({
    start_time: z.string().describe("Start time in HH:MM:SS.MS format"),
    end_time: z.string().describe("End time in HH:MM:SS.MS format"),
    url: z.string().describe("URL of the extracted segment")
  })).describe("List of extracted segments")
});

// Initialize the VLMRun client
const client = new VlmRun({
  apiKey: "<VLMRUN_API_KEY>",
  baseURL: "https://api.vlm.run/v1"
});

// Extract highlights with structured output
const response = await client.agent.completions.create({
  model: "vlmrun-orion-1:auto",
  messages: [
    {
      role: "user",
      content: [
        { type: "text", text: "Extract the 3 best moments from this video, including the start and end times of each moment." },
        { type: "video_url", video_url: { url: "https://storage.googleapis.com/vlm-data-public-prod/hub/examples/video.transcription/bakery.mp4" } }
      ]
    }
  ],
  response_format: {
    type: "json_schema",
    schema: zodToJsonSchema(HighlightExtractionResponseSchema)
  }
});

const result = HighlightExtractionResponseSchema.parse(JSON.parse(response.choices[0].message.content));
3. Time-Based Trimming
Trim the video from 10 seconds to 30 seconds
20-second trim.
from vlmrun.client import VLMRun

# Initialize the VLMRun client
client = VLMRun(api_key="<VLMRUN_API_KEY>")

# Trim video
response = client.agent.completions.create(
    model="vlmrun-orion-1:auto",
    messages=[
        {
            "role": "user",
            "content": [
                {"type": "text", "text": "Trim the video from 10 seconds to 30 seconds"},
                {"type": "video_url", "video_url": {"url": "https://storage.googleapis.com/vlm-data-public-prod/hub/examples/video.transcription/bakery.mp4"}}
            ]
        }
    ]
)

print(response.choices[0].message.content)
# >>> {"start_time": "00:00:10.000", "end_time": "00:00:30.000", "url": "https://.../trimmed.mp4"}
from vlmrun.client import VLMRun
from pydantic import BaseModel, Field

# Define the response schema
class VideoResponse(BaseModel):
  start_time: str = Field(..., description="Start time in HH:MM:SS.MS format")
  end_time: str = Field(..., description="End time in HH:MM:SS.MS format")
  url: str = Field(..., description="URL of the trimmed video")

# Initialize the VLMRun client
client = VLMRun(api_key="<VLMRUN_API_KEY>")

# Trim video with structured output
response = client.agent.completions.create(
    model="vlmrun-orion-1:auto",
    messages=[
        {
            "role": "user",
            "content": [
                {"type": "text", "text": "Trim the video from 10 seconds to 30 seconds"},
                {"type": "video_url", "video_url": {"url": "https://storage.googleapis.com/vlm-data-public-prod/hub/examples/video.transcription/bakery.mp4"}}
            ]
        }
    ],
    response_format={"type": "json_schema", "schema": VideoResponse.model_json_schema()}
)

# Validate the response
result = VideoResponse.model_validate_json(response.choices[0].message.content)
import { VlmRun } from "vlmrun";

const client = new VlmRun({
  apiKey: "<VLMRUN_API_KEY>",
  baseURL: "https://api.vlm.run/v1"
});

const response = await client.agent.completions.create({
  model: "vlmrun-orion-1:auto",
  messages: [
    {
      role: "user",
      content: [
        { type: "text", text: "Trim the video from 10 seconds to 30 seconds" },
        { type: "video_url", video_url: { url: "https://storage.googleapis.com/vlm-data-public-prod/hub/examples/video.transcription/bakery.mp4" } }
      ]
    }
  ]
});

console.log(response.choices[0].message.content);
import { VlmRun } from "vlmrun";
import { z } from "zod";
import { zodToJsonSchema } from "zod-to-json-schema";

// Define the response schema with Zod
const VideoResponseSchema = z.object({
  start_time: z.string().describe("Start time in HH:MM:SS.MS format"),
  end_time: z.string().describe("End time in HH:MM:SS.MS format"),
  url: z.string().describe("URL of the trimmed video")
});

// Initialize the VLMRun client
const client = new VlmRun({
  apiKey: "<VLMRUN_API_KEY>",
  baseURL: "https://api.vlm.run/v1"
});

// Trim video with structured output
const response = await client.agent.completions.create({
  model: "vlmrun-orion-1:auto",
  messages: [
    {
      role: "user",
      content: [
        { type: "text", text: "Trim the video from 10 seconds to 30 seconds" },
        { type: "video_url", video_url: { url: "https://storage.googleapis.com/vlm-data-public-prod/hub/examples/video.transcription/bakery.mp4" } }
      ]
    }
  ],
  response_format: {
    type: "json_schema",
    schema: zodToJsonSchema(VideoResponseSchema)
  }
});

const result = VideoResponseSchema.parse(JSON.parse(response.choices[0].message.content));
FAQ
What video formats are supported for trimming?
What video formats are supported for trimming?
- MP4
- MOV (QuickTime)
- AVI
- MKV (Matroska)
- WebM
- Trimmed segments keep the source quality.
What are the best practices for frame sampling?
What are the best practices for frame sampling?
- Sample at a fixed interval, such as every 1-5 seconds.
- Sample keyframes.
- Sample on scene changes.
- Set the interval for the analysis you need.
How precise is the time-based trimming?
How precise is the time-based trimming?
- Cuts use millisecond timestamps.
- Cuts align to the nearest keyframe.
- Cut points are detected automatically.
- Quality stays without re-encoding when possible.
Try Video Trimming
Trim video and sample frames.